


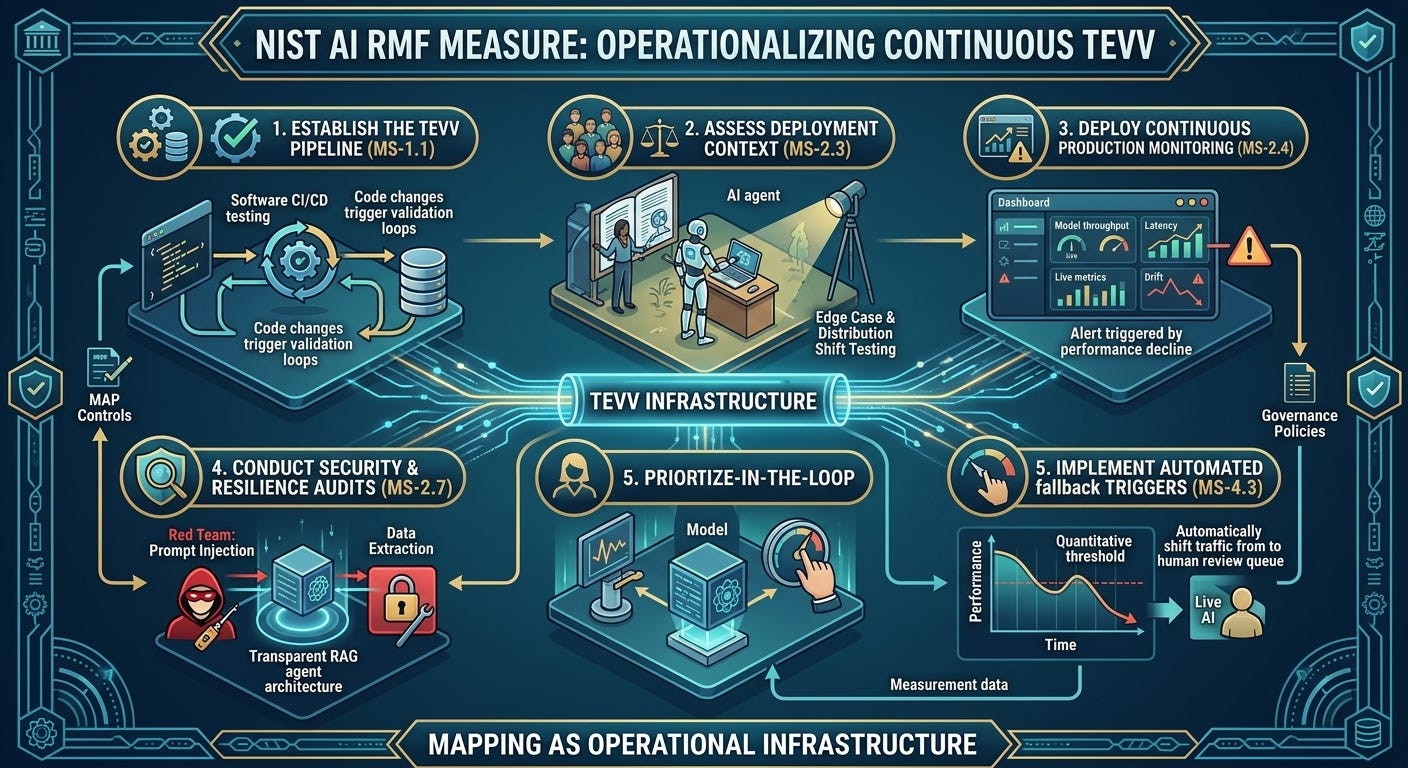
The Govern function tells you who’s accountable. The Map function tells you what you’re accountable for. The Measure function demands something far more rigorous: empirical proof that your AI system performs safely, accurately, and equitably in production. Most enterprise teams treat AI testing as a one-and-done validation exercise before release. NIST’s Measure function requires a continuous Test, Evaluation, Verification, and Validation (TEVV) infrastructure: standardized metrics, rigor matched evaluation tools, feedback mechanisms for socio-technical impacts, and formal tracking of systemic drift.
Twenty two subcategories across four core categories. Without them, Govern operates on blind faith, Map remains an unverified spreadsheet, and Manage has no operational triggers to act upon.
Breakdown of the 22 NIST AI RMF MEASURE Controls
The Measure function splits into four distinct categories containing 22 subcategories total:
MEASURE 1: Appropriate Methods and Metrics Are Identified and Employed
MEASURE 1.1 – Risk-based metric selection matches system context and socio-technical impacts.
MEASURE 1.2 – Metrics are regularly assessed for ongoing appropriateness and validity.
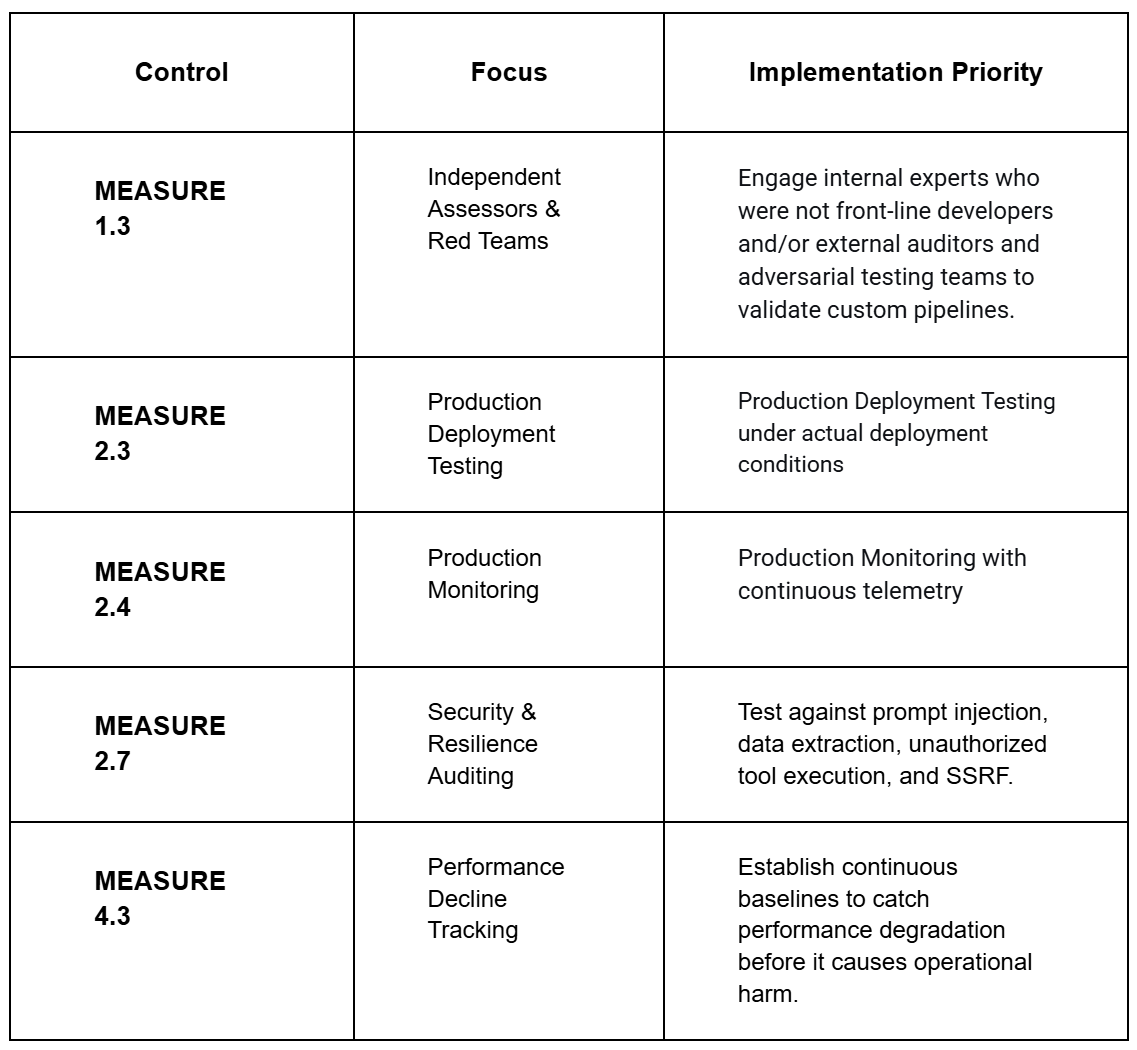
MEASURE 1.3 –Internal experts who did not serve as front-line developers and/or independent assessors are engaged to conduct regular assessments.
MEASURE 2: AI Systems Are Evaluated for Trustworthy Characteristics
MEASURE 2.1 – TEVV tools, datasets, and methodologies are documented and maintained.
MEASURE 2.2 – Human subject evaluations and user impact studies are conducted ethically.
MEASURE 2.3 – System performance is evaluated under actual deployment conditions, not just synthetic tests.
MEASURE 2.4 – Production monitoring is established to track performance and operational metrics continuously.
MEASURE 2.5 – System validity, reliability, and accuracy are demonstrated across diverse inputs.
MEASURE 2.6 – Safety evaluations identify potential failure modes, hazards, and misuse scenarios.
MEASURE 2.7 – Security and resilience evaluations, as identified in the MAP function, test vulnerability to prompt injection, extraction, and data leakage.
MEASURE 2.8 – Transparency and accountability mechanisms verify system governance trails.
MEASURE 2.9 – Explainability and interpretability evaluations ensure outputs are understandable to operators.
MEASURE 2.10 – Privacy risk assessments evaluate exposure of sensitive or personal data.
MEASURE 2.11 – Fairness, bias, and demographic disparity evaluations are routinely executed.
MEASURE 2.12 – Environmental and resource footprint impacts are tracked against organizational goals.
MEASURE 2.13 – Effectiveness of the overall TEVV process is periodically reviewed and updated.
MEASURE 3: Mechanisms for Tracking Feedback Are Documented
MEASURE 3.1 – Approaches for identifying and tracking emergent risks in production are operationalized.
MEASURE 3.2 – Difficult-to-assess or qualitative risks are systematically tracked over time.
MEASURE 3.3 – Feedback and appeal mechanisms exist for end users and affected stakeholders.
MEASURE 4: Measurement Efficacy Feedback Is Integrated
MEASURE 4.1 – Measurement outcomes directly inform deployment context adjustments and Map controls.
MEASURE 4.2 – Domain experts validate measurement results before executive or operational actions are taken.
MEASURE 4.3 – Mechanisms are in place to track performance improvements and degradations over time in consultation with relevant AI actors, including affected communities, to identify systemic drift.
The Controls That Break Most Organizations: MEASURE 1.3 & 2.7
MEASURE 1.1 through 2.5 and 2.8 through 2.13 require basic engineering discipline. MEASURE 1.3 (Independent Assessors) and MEASURE 2.7 (Security & Resilience Evaluation) fail in production because enterprise teams evaluate models under static lab conditions rather than dynamic, adversarial environments.
Consider a defense contractor deploying a retrieval-augmented generation (RAG) agent to query technical manuals and maintenance logs. During initial validation (MEASURE 2.5), the system scored 94% accuracy on synthetic benchmarks. Six months after deployment, field technicians began reporting subtle hallucinations in safety critical procedures.
Because the team evaluated the system only prior to launch, they missed how vector database updates introduced data distribution shifts. Worse, they lacked an independent red-teaming harness (MEASURE 1.3) or security testing pipeline (MEASURE 2.7) to detect indirect prompt injection via ingested maintenance PDFs. The system passed pre-deployment QA, but failed in the field because no continuous TEVV pipeline monitored performance drift or security boundaries.
That is the gap MEASURE 1.3 and 2.7 are built to close:
Static benchmarks vs. dynamic reality. Lab benchmarks (like MMLU or HumanEval) do not reflect proprietary enterprise workflows. MEASURE 2.3 requires evaluation against real world deployment conditions and edge cases, not pristine test sets.
The illusion of vendor safety. Relying on a foundation model vendor’s system card is not compliance. MEASURE 1.3 requires independent, third-party TEVV and red-teaming of the complete application stack, including custom RAG pipelines, fine tuned adapters, and tool integration layers.
Lack of automated revocation triggers. Measuring a flaw without an
automated response is useless. MEASURE 4.3 demands tracking performance decline so that degradation automatically triggers fallback routing or human-in-the-loop intervention.
Priority Controls for Audit Season
These five carry the heaviest audit weight and the highest probability of a compliance finding if undocumented:
The Remaining 17 (Audit Checklist)
1.1 Risk-based metrics selected to match operational context.
1.2 Appropriateness of selected metrics periodically re-evaluated.
2.1 TEVV documentation and testing harnesses maintained.
2.2 Ethical oversight established for human subject evaluations.
2.5 Accuracy and reliability demonstrated across edge-case data.
2.6 Safety hazards and misuse risks formally evaluated.
2.8 Audit trails and decision logs verified for completeness.
2.9 Explainability outputs vetted for operator comprehension.
2.10 Privacy assessments executed against vector databases and inputs.
2.11 Bias and fairness metrics evaluated across demographic outputs.
2.12 Compute and environmental impacts tracked against corporate targets.
2.13 Effectiveness of internal TEVV practices regularly audited.
3.1 Tracking processes established for unexpected operational risks.
3.2 Qualitative and hard-to-measure risks systematically logged.
3.3 End-user appeal channels and feedback loops deployed.
4.1 Measurement results used to update Map risk categories.
4.2 Subject matter experts review evaluation data before deployment decisions.
Measure as Operational Infrastructure
Working through all 22 subcategories moves Measure from a periodic manual QA task to a continuous, automated telemetry pipeline. Organizations that integrate Measure controls directly into their CI/CD and production monitoring systems build AI deployments that survive rigorous federal and state regulatory audits. When auditors ask for proof of trustworthiness, you hand them real-time telemetry—not outdated pre-launch promises.
When you last ran continuous evaluation on your production AI stack, did your performance metrics match your pre-launch benchmarks?