


Then what?
If your honest answer is “we assumed it was still working fine,” you’ve just described the most common failure in AI governance. Testing once isn’t measurement. Measurement is continuous. It’s knowing whether your AI system is performing as intended right now, not assuming it is based on historical validation. This is where MEASURE begins: validating that your AI system is doing what you built it to do, detecting when it stops, and having a process to respond when something goes wrong.
Why Continuous Measurement Matters
MEASURE closes the loop on NIST AI RMF.
GOVERN gave you roles and oversight. MAP gave you visibility into what systems exist. MEASURE ensures those systems are still safe to operate.
Here’s what happens without it:
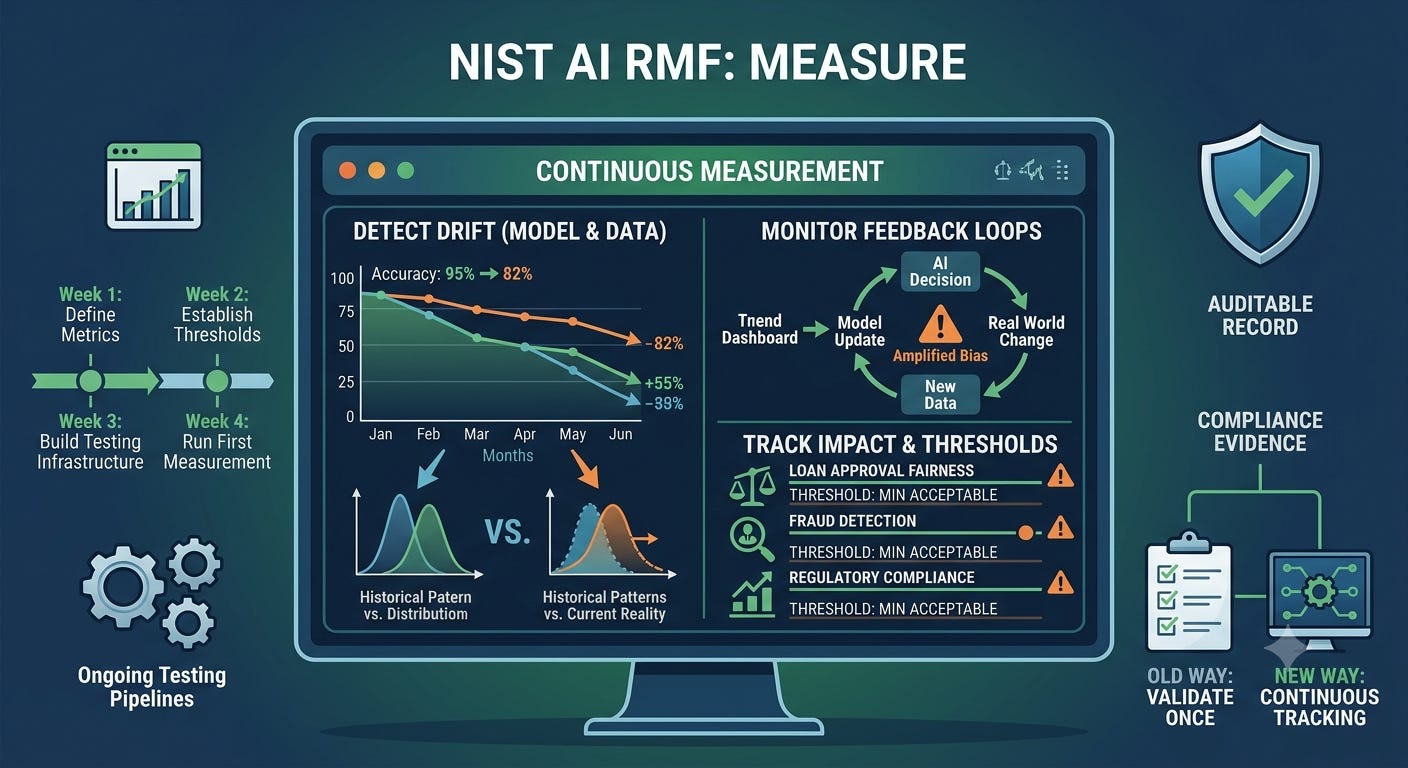
Model drift. Your training data looked like customer X six months ago. Now customer X behaves differently. Your model learned on historical patterns that no longer match reality. Performance drops silently. Your system is still making decisions, but worse ones.
Data drift. The distribution of inputs to your model has shifted. Maybe your customer base changed. Maybe seasonality hit differently. Maybe an upstream system started sending data in a new format. Your model wasn’t trained on this input space and performs unpredictably.
Feedback loops. Your AI system makes a decision (approve a loan, rank a candidate, flag a fraud case). That decision changes the real world, which generates new data, which your system learns from. If the decision was biased, the feedback loop amplifies the bias over time.
Silent failures. Traditional IT monitors uptime; AI governance monitors efficacy. Most AI systems don’t crash, they degrade. Performance drops 10%, then 15%. By the time you notice, weeks of decisions were made below your acceptable threshold.
For regulated industries, finance, healthcare, employment, this isn’t just operational. It’s a compliance violation. Regulators expect continuous measurement and documented evidence that controls are working.
What MEASURE Requires
Measurement has three components:
Define your thresholds. Before you can measure, you need to know what “acceptable” looks like. What’s your minimum accuracy? Your maximum false positive rate? Your fairness metric for protected classes? What triggers an alert? These thresholds come directly from your governance framework (GOVERN) and your risk map (MAP). high-stakes decisions get tighter thresholds. Lower stakes decisions get more tolerance. Document these. Audit them regularly.
Test continuously. Validation isn’t a one time event. You need an ongoing testing process that runs on a schedule weekly, monthly, or real-time depending on risk and volatility. This includes:
Performance testing against held-out test sets to catch model drift
Input distribution monitoring to catch data drift
Fairness testing on protected attributes
Performance segmentation (does your model degrade for specific groups?)
Edge case testing for high-impact decisions
Most organizations skip this because it sounds expensive. It isn’t. A few hours of engineering to build a testing pipeline pays for itself the first time it catches a problem before a regulator does.
Track impact. Measurement isn’t just metrics. It’s documenting the real-world impact of your AI system. Is it making the decisions you intended? Are there unintended consequences? Are specific populations affected differently? Impact tracking requires feedback loops. When your AI denies a loan, does the customer appeal? When it flags fraud, how often is the flag correct? When it ranks candidates, do the recommended hires actually perform well? These feedback signals tell you whether your model is working in practice, not just in testing.
The Practical Starting Point
You don’t need to instrument everything today.
Start here:
Week one: Define your metrics. Sit with your governance and engineering teams. For each high-risk AI system, answer: What metric proves this system is working as intended? Accuracy? Fairness? Latency? Business impact? Write it down. This becomes your North Star.
Week two: Establish your thresholds. For each metric, what’s the minimum acceptable performance? What triggers an alert? What triggers an escalation to leadership or regulators? Document these. Get sign-off from compliance and your business owner.
Week three: Build or purchase testing infrastructure. You need a way to measure your metrics continuously. This might be a Python script that runs daily, a cloud monitoring dashboard, or a dedicated platform. The tool matters less than consistency. You’re creating an auditable record of system performance over time.
Week four: Run your first measurement. Measure your high risk systems against your thresholds. Document what you find both good and problematic. If you find gaps, add them to your risk register. If everything passes, you now have a baseline to compare against next month.
This isn’t perfect measurement. It’s operational measurement. It runs continuously. It’s auditable. It catches drift before it becomes a crisis.
The Better Way (Coming Soon)
Right now, measurement lives in spreadsheets, dashboards scattered across teams, and email escalations that get missed. Continuous measurement requires someone to actually run the tests, track the metrics, and maintain the records, every week, every month.
That’s exactly the problem we’re solving with Enclave. I’m building a platform that turns MEASURE from a quarterly obligation into continuous tracking. Document your thresholds, maintain your test results, track your AI system performance against your metrics, and generate audit-ready reports on demand, all encrypted, offline, on your machine.
For now, the manual approach works. The point is to start measuring.
Where This Leaves You
GOVERN gave you accountability. MAP gave you visibility. MEASURE gives you early warning. MANAGE closes the cycle by prioritizing and responding to the risks you’ve identified.
You now have the full cycle: Define your controls and governance, map your AI systems and data flows, measure their performance continuously, and manage the risks you uncover.
The framework is yours to operationalize. If you could measure one thing about your AI systems starting today, what would it be?