


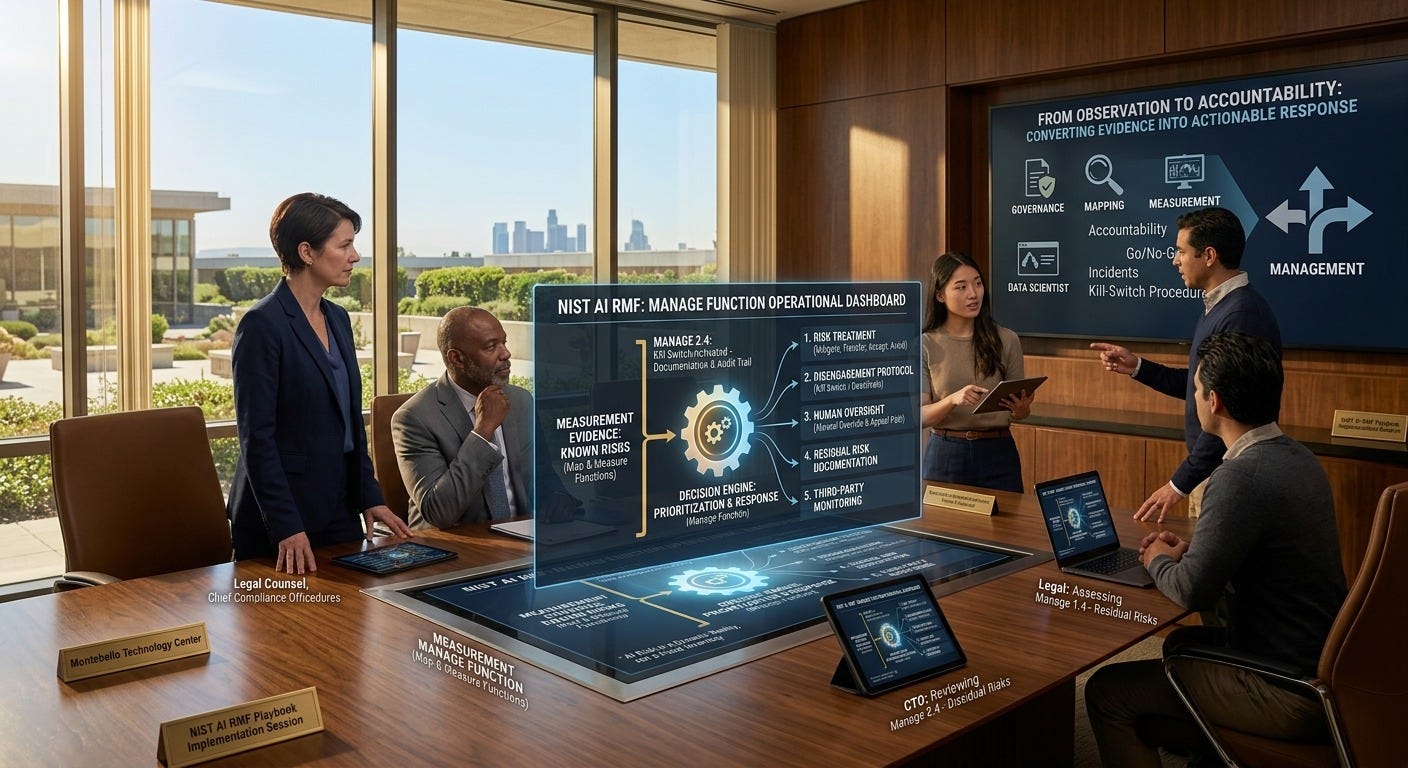
Your measurement plan is complete. Your dashboards show exactly where risks exist. Your team has documented evidence that the AI system is secure, fair, and reliable. So why does your legal team still look worried every time you mention AI in a meeting?
You’re not alone. The most common implementation failure across organizations looks remarkably similar: teams complete Govern and Map, produce a shiny policy and an AI inventory, then carefully execute Measure and generate beautiful evidence of risk. Then they quietly assume that evidence somehow manages itself, and call it a day.
But that’s not what Manage actually means.
Manage is where measurement becomes a decision. And for most companies, that’s precisely where the wheels come off.
What Is the Manage Function?
The Manage function covers the treatment, response, monitoring, and continuous improvement after risk has been identified and measured. It takes the knowledge from the Map and the evidence from the Measure function and turns them into action: prioritization of risk, selection of treatment strategies, incident response, and ongoing oversight.
As NIST itself puts it: Manage is where AI risks are prioritized, responded to, and managed and where strategies to maximize benefits and minimize negative impacts are planned, prepared, and implemented.
A Quick Note on the Subcategory Counts
To avoid confusion for strict auditors: the core NIST AI RMF 1.0 document (NIST AI 100-1) defines the Manage function as 4 categories and 14 core subcategories.
However, the interactive NIST AI RMF Playbook and its expanded crosswalks break those 14 subcategories into a more granular set of actionable items to provide comprehensive coverage. This article references the Playbook’s actionable depth, but know that both counts are technically correct depending on which document you are holding.
The Four Manage Categories
MANAGE 1: AI risks are prioritized, responded to, and managed
This category covers the go/no-go decision and the explicit choice of how to handle each identified risk:
MANAGE 1.1: A determination is made as to whether the AI system achieves its intended purposes and whether development or deployment should proceed
MANAGE 1.2: Treatment of documented AI risks is prioritized based on impact, likelihood, and available resources
MANAGE 1.3: Responses to high-priority risks are developed, planned, and documented. Risk response options can include mitigating, transferring, avoiding, or accepting
MANAGE 1.4: Negative residual risks to downstream acquirers and end users are documented
The artifact: An explicit go/no-go decision with documented risk treatment plans and residual risk disclosure.
MANAGE 2: Strategies to maximize benefits and minimize negative impacts
This category covers the operational side resourcing, sustainment, and the mechanisms to respond when things go wrong:
MANAGE 2.1:Resources required to manage AI risks are taken into account, along with viable non-AI alternatives, a critical governance question asking not just “how do we deploy this AI?” but “should we deploy AI at all, or is a non-AI solution more appropriate for this context?”
MANAGE 2.2: Mechanisms are in place to sustain the value of deployed AI systems
MANAGE 2.3: Procedures are followed to respond to and recover from previously unknown risks when identified
MANAGE 2.4: Mechanisms and responsibilities are in place to supersede, disengage, or deactivate systems that demonstrate performance inconsistent with intended use
MANAGE 3: AI risks and benefits from third-party entities are managed
This category addresses the supply chain reality of modern AI:
MANAGE 3.1: AI risks and benefits from third-party resources are regularly monitored, and risk controls are applied and documented
MANAGE 3.2: Pre-trained models used for development are monitored as part of regular monitoring and maintenance
MANAGE 4: Risk treatments, response and recovery, communication plans
This category closes the loop with communication and continuous improvement:
MANAGE 4.1: Post-deployment monitoring, incident response, decommissioning procedures, and mechanisms for user input, feedback, appeal, and override are in place, along with formal change management processes
MANAGE 4.2: Measurable activities for continual improvements are integrated into AI system updates, with regular engagement of interested parties, including relevant AI actors
MANAGE 4.3: Incidents and errors are communicated to relevant AI actors, and processes for tracking, responding to, and recovering are followed and documented
Why Manage Fails in Practice
1. The “Evidence-to-Action” Gap
One of the biggest misconceptions: teams assume Manage is just “risk response documentation.” But Manage is not a passive document, it’s an active decision-making engine. Many organizations are very good at measuring risk and producing beautiful dashboards, but much weaker at actually acting on that evidence. Your model has a fairness issue? Your dashboard shows it. Now what? Manage is where the “now what” gets answered with an actual decision and an accountable owner.
2. The Missing Human Oversight
NIST places equal weight on human-in-the-loop operational structures as it does on technical controls. This includes appeal mechanisms that give affected parties recourse, manual override capabilities that allow humans to overrule AI decisions, and clearly documented authority levels for who can intervene and when. Yet in practice, organizations often build sophisticated monitoring infrastructure and stop there, leaving humans without the procedural authority or pathways to actually act on what the monitoring reveals. The system alerts, but no one has the documented authority to hit the stop button, or no one has told affected users how to challenge an adverse decision.
3. The Missing Kill Switch
The model drifts. Performance degrades. The system starts behaving in ways inconsistent with its intended use. And then everyone panics because no one thought to build a documented procedure for disengagement. Manage 2.4 explicitly requires mechanisms to “supersede, disengage, or deactivate” systems that demonstrate outcomes inconsistent with intended use. For most organizations, this is the first thing to go when budgets tighten, and the first thing they regret when something goes wrong.
4. The “Unknown Risk” Surprise
Your team has documented every known risk. All the measurement evidence is in place. Then something unexpected happens: a novel prompt injection, a weird pattern in production data, a capability your model developed that no one anticipated. Manage 2.3 requires procedures to respond to and recover from previously unknown risks. The problem is, many organizations treat risk as a fixed inventory rather than a dynamic reality.
5. Third-Party Blind Spots
AI systems rarely live in isolation. They rely on foundation models, pre-trained weights, and third-party APIs. But vendor risk monitoring is often an afterthought. Manage 3.1 requires that AI risks and benefits from third-party resources are regularly monitored and controls are applied and documented. When the foundation model you’re using gets a new version or a security advisory, do you know? And more importantly, can you prove you know?
6. The Documentation Disconnect
NIST explicitly requires that “residual risk is documented and disclosed to downstream acquirers and end users”. Yet in practice, residual risk acceptance is often implicit and undocumented. A decision to deploy despite known risks needs to be reviewable, not just assumed. What gets documented is what gets governed, and what gets governed is what gets managed.
7. The Forgotten Affected Communities
When things go wrong, who needs to know? Manage 4.3 requires that incidents and errors are communicated not just to internal AI actors but to affected communities the people whose lives, livelihoods, or rights are impacted by AI decisions. Many organizations treat communication as an internal exercise, forgetting that transparency to affected populations is a core tenet of trustworthy AI.
What the Playbook Actually Says to Do
The NIST AI RMF Playbook provides suggested actions for each Manage subcategory. The most critical include:
Make an explicit go/no-go decision: Not a default-to-ship. A documented determination that the AI system achieves its intended purposes
Prioritize based on data: Use impact, likelihood, and resource constraints not whoever shouted loudest in the last review
Choose a response strategy: For each high-priority risk, document whether you’re mitigating, transferring, avoiding, or accepting it
Document residual risk: Make implicit acceptance explicit and reviewable
Build a documented kill-switch: With named owners and clear triggers for disengaging or deactivating
Plan for the unknown: Have a documented procedure for when something new surfaces including triage, containment, communication, and remediation
Monitor your vendors: Third-party risk posture on a recurring cadence, with corresponding controls documented as applied
Include AI assets in backup and recovery: Model artifacts, training snapshots, and vector databases need explicit inclusion in backup scope and regular recovery testing
Practical Controls That Work
Concrete Manage function controls include:
Risk and Decision Governance:
Risk register with accountable owners: Every unresolved or accepted risk has an accountable owner and a documented rationale
Explicit go/no-go documentation: A formal artifact signed by accountable executives, not just a product manager’s nod
Residual risk disclosure statements: Clear documentation of what risks remain and how they’ve been communicated to downstream users and affected communities
Human Oversight and Intervention:
Human-in-the-loop override and appeal protocols: Standard operating procedures defining when and how human operators can override AI decisions—including confidence threshold triggers, delegated authority levels, time-to-respond SLAs, and documentation requirements for each override action. Appeal pathways for affected parties are similarly documented with clear ownership and resolution timelines. These protocols ensure that human judgment is not just available in theory but operationalized in practice, with clear escalation paths when automated systems flag uncertain or high-stakes decisions
Manual override protocols: Clear authority levels specifying who can overrule AI decisions and under what circumstances, with documented approval chains and audit trails for every override event
Appeal processing workflows: Documented pathways for affected parties to challenge AI decisions, with defined SLAs, escalation paths, and remediation procedures
Human-in-the-loop checkpoints: For high-impact decisions, documented procedures requiring human review before action is taken, with clear criteria defining which decisions trigger human review
Incident and Response Infrastructure:
Incident response playbooks for AI: Sentinel-driven or similar automated incident response that connects findings to applications, owners, policies, and remediation workflows
Disengagement procedures: Documented protocols to safely remove AI systems from operation, either temporarily or permanently, with redundant or backup systems in place
Continuous monitoring infrastructure: 24x7 monitoring of AI behavior, with quantitative and qualitative baselines for each AI system
Third-Party and Supply Chain:
Third-party risk monitoring: Recurring vendor assessments that include foundation model monitoring, deprecation tracking, and security event monitoring
Model provenance tracking: Documentation of where pre-trained models originated and how they are monitored post-deployment
Continuous Improvement and Communication:
Monthly risk register review: With executive escalation for new high-risk findings
Backup and recovery testing for AI assets: Model artifacts, training data versions, and vector databases explicitly named in backup scope
Stakeholder engagement cadence: Regular engagement with interested parties, including affected communities and relevant AI actors, as required by Manage 4.2
Incident communication templates: Pre-approved templates and distribution lists for notifying both internal AI actors and affected communities when incidents occur, ensuring timely and consistent disclosure
The Real Question
Here’s the uncomfortable truth: Manage is the function that turns evidence into accountability. Govern sets the policy. Map identifies the risks. Measure produces the evidence. Without Manage, the other three functions operate on observation rather than action.
In enterprise environments, the question is rarely: “Do we know the risks?” The real question is: “What are we doing about them, and can we prove it?”
So here’s the question for you and your team:
If your AI system started behaving unpredictably tomorrow and producing outputs inconsistent with its intended purpose, drifting into fairness violations, or showing signs of a novel security vulnerability could you disengage it? And more importantly, could you prove that you had the capability to do so all along? Do you have the incident response procedure, the documented kill switch, and the communication plan ready? Or are you operating on hope rather than preparedness?
Because in AI risk management, hope is not a response strategy. And Manage is where readiness becomes action.