


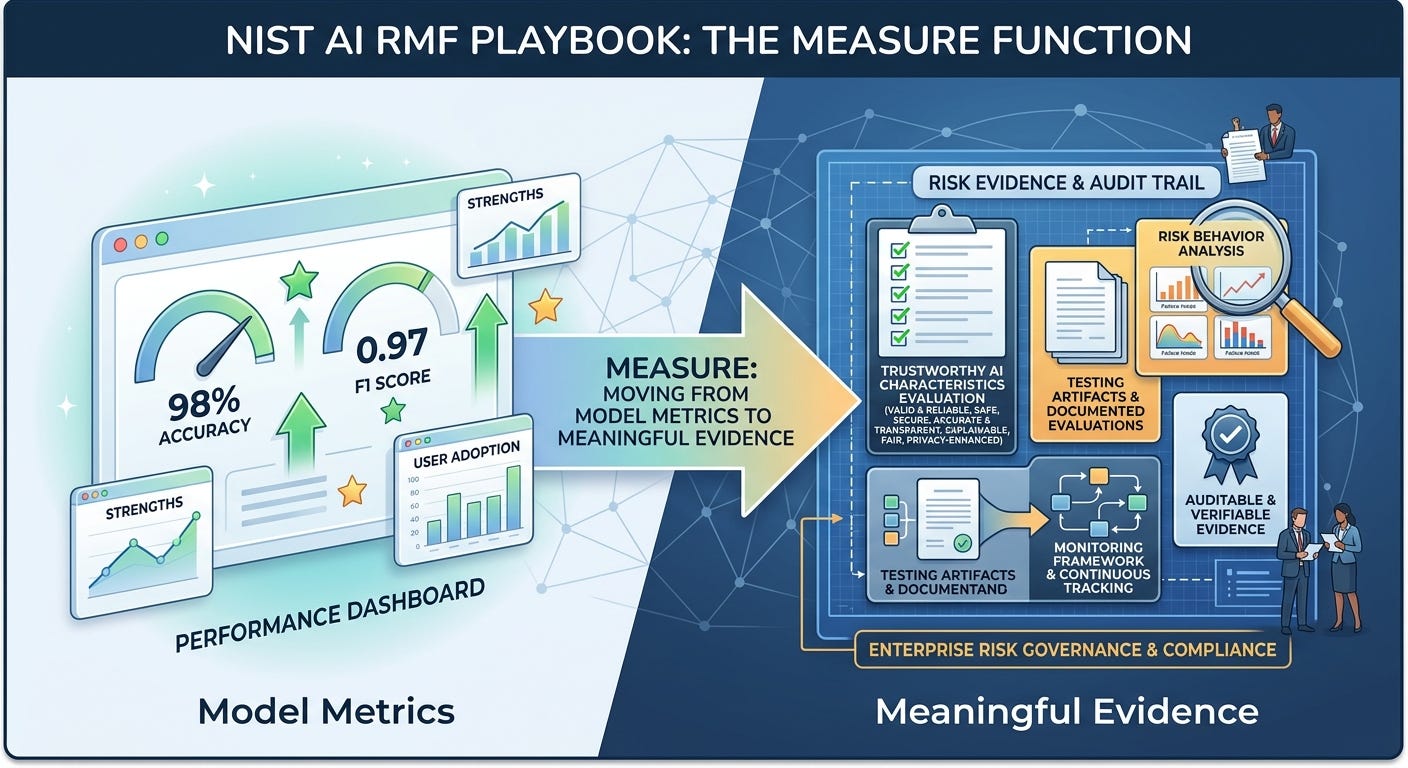
You’re not alone. The most common implementation failure across organizations looks remarkably similar: teams complete Govern and Map on paper, produce a shiny policy and an AI inventory, and assume they’re done. Then they quietly equate Measure with a few model metrics, accuracy, precision, maybe hallucination rates and call it a day.
But that’s not what Measure actually means.
Measure is where risk awareness becomes auditable evidence. And for most companies, that’s precisely where the wheels come off.
What Is the Measure Function?
The Measure function employs quantitative, qualitative, or mixed-method tools, techniques, and methodologies to analyze, assess, benchmark, and monitor AI risk and related impacts. It uses knowledge from the Map function and feeds directly into Manage measurement outcomes are utilized to assist risk monitoring and response efforts.
As NIST itself puts it: “If you cannot measure it, you cannot improve it”.
A Quick Note on the Subcategory Counts
To avoid confusion for strict auditors: the core NIST AI RMF 1.0 document (NIST AI 100-1) defines the Measure function as 4 categories and 17 core subcategories, with MEASURE 2 containing 7 subcategories.
However, the interactive NIST AI RMF Playbook and its expanded crosswalks break those 7 subcategories into 22 distinct actionable items (with 13 under MEASURE 2) to provide granular coverage of all seven trustworthy AI characteristics. This article references the Playbook’s actionable depth, but know that both counts are technically correct depending on which document you are holding.
The Four Measure Categories
MEASURE 1: Appropriate methods and metrics are identified and applied This category establishes that you’ve identified what to measure and how to measure it:
MEASURE 1.1: Approaches and metrics for AI risks are selected starting with the most significant risks
MEASURE 1.2: Metrics and controls are regularly assessed and updated
MEASURE 1.3: Independent assessors and domain experts are involved in regular assessments
The artifact: a measurement plan per AI system documenting which risks are being measured, which metrics are tracked, and which baselines apply.
MEASURE 2: AI systems are evaluated for trustworthy characteristics
This is the heavy lift, 13 subcategories covering actual evaluation against the seven trustworthy AI characteristics: valid and reliable, safe, secure and resilient, accountable and transparent, explainable and interpretable, privacy enhanced, and fair.
Key subcategories include:
MEASURE 2.1: Test sets, metrics, and TEVV tools are documented
MEASURE 2.3: Performance is measured and demonstrated in deployment-like conditions
MEASURE 2.4: Functionality and behavior are monitored in production
MEASURE 2.6: Safety risks are evaluated regularly residual risk must not exceed tolerance
MEASURE 3: Mechanisms for tracking identified AI risks over time
Risk isn’t static, neither should your measurement be. This category covers continuous monitoring of AI risks and impacts, tracking risk over the AI lifecycle, and updating risk assessments as the system evolves.
MEASURE 4: Feedback about efficacy of measurement
This category ensures measurement itself is being measured, with feedback mechanisms, domain expert validation, and continuous improvement of measurement methods.
Why Measure Fails in Practice
1. The “Performance vs. Risk” Blind Spot
One of the biggest misconceptions: teams assume Measure means model performance metrics accuracy, precision, F1. But in the NIST AI RMF, Measure is about evidence that the system’s risks are understood, evaluated, and continuously monitored. Many organizations are very good at measuring model performance, but much weaker at measuring risk behavior. Performance metrics tell you how well the AI works. Risk measurement tells you how the AI fails, and that’s usually what enterprise governance teams care about most.
2. The Evidence Gap
The model works. The pilot succeeds. Users like the system. But when security, legal, or compliance teams start asking questions, the organization realizes something important: They don’t actually have structured evidence of risk evaluation. No formal testing artifacts. No documented evaluations. No monitoring framework.
3. Measure Without a Real Map
Choosing metrics before understanding context usually measures the wrong thing. If your Map function didn’t properly identify risks, your Measure function will produce pretty numbers that mean nothing.
4. The Data Infrastructure Gap
You can’t measure what you can’t observe. Most organizations lack the runtime visibility needed to benchmark risk consistently. Measure assumes you can produce evidence that your data protection controls are in place and working but backup and recovery scope rarely covers AI workloads like model artifacts, training snapshots, and vector databases.
5. No Continuous Monitoring
Many organizations treat measurement as a one-time pre-deployment activity. But the Measure function emphasizes that evaluation should be ongoing throughout the AI lifecycle, not just a one time pre-deployment gate. Performance drift, bias drift, and security vulnerabilities emerge over time.
6. The Reliable Metrics Challenge
NIST itself explicitly acknowledges that the “current lack of consensus on robust and verifiable measurement methods for risk and trustworthiness... is an AI risk measurement challenge“. This isn’t just a theoretical gap, it’s a massive friction point in implementation. The framework also warns that generic measurement approaches can be “oversimplified, gamed, lack critical nuance, [and] become relied upon in unexpected ways”.
What the Playbook Actually Says to Do
The NIST AI RMF Playbook provides suggested actions for each Measure subcategory. The most critical include:
Select metrics based on risk, not convenience choose what matters, not what’s easy to measure
Document what you cannot measure, if a trustworthiness characteristic can’t be measured, document why
Test before deployment and regularly while in operation
Instrument the system for measurement and tracking maintain histories of inputs, outputs, and performance
Engage independent assessors, people who didn’t build the system
Run continuous bias, performance, and security tests against production data
Practical Controls That Work
Concrete Measure function controls include:
Measurement plan owner, a named individual (typically the AI system’s product manager or risk owner) who maintains the plan, validates it against the system’s evolution, and engages stakeholders on a documented cadence
Offline evaluation datasets for pre-deployment testing
Continuous monitoring for model drift, establishing quantitative and qualitative baselines for each AI system based on your organization’s risk thresholds
Adversarial testing and red teaming
Bias and fairness testing against representative populations
Performance benchmarking under deployment-like conditions
Interaction level visibility with full conversation context so risk is measured against real usage instead of a questionnaire
Documented test plans accessible to auditors
Third party model and vendor risk assessments
The Real Question
Here’s the uncomfortable truth: Measure is the function that produces the operational evidence the other three functions depend on. Govern sets the policy. Map identifies the risks. Manage responds to the measurements. Without Measure, the other three functions operate on assertion rather than evidence.
In enterprise environments, the question is rarely: “Does the AI work?” The real question is: “Can we prove that the risks of this AI are understood and managed?”
So here’s the question for you and your team:
If a regulator, auditor, or customer asked you tomorrow to produce documented evidence that your AI system is secure, fair, and reliable, not just a policy that says it should be, but actual test results, monitoring data, and measurement artifacts could you produce it? Or are you operating on assertion rather than evidence?
Because in AI risk management, hope is not a measurement strategy. And Measure is where assertion becomes evidence.