


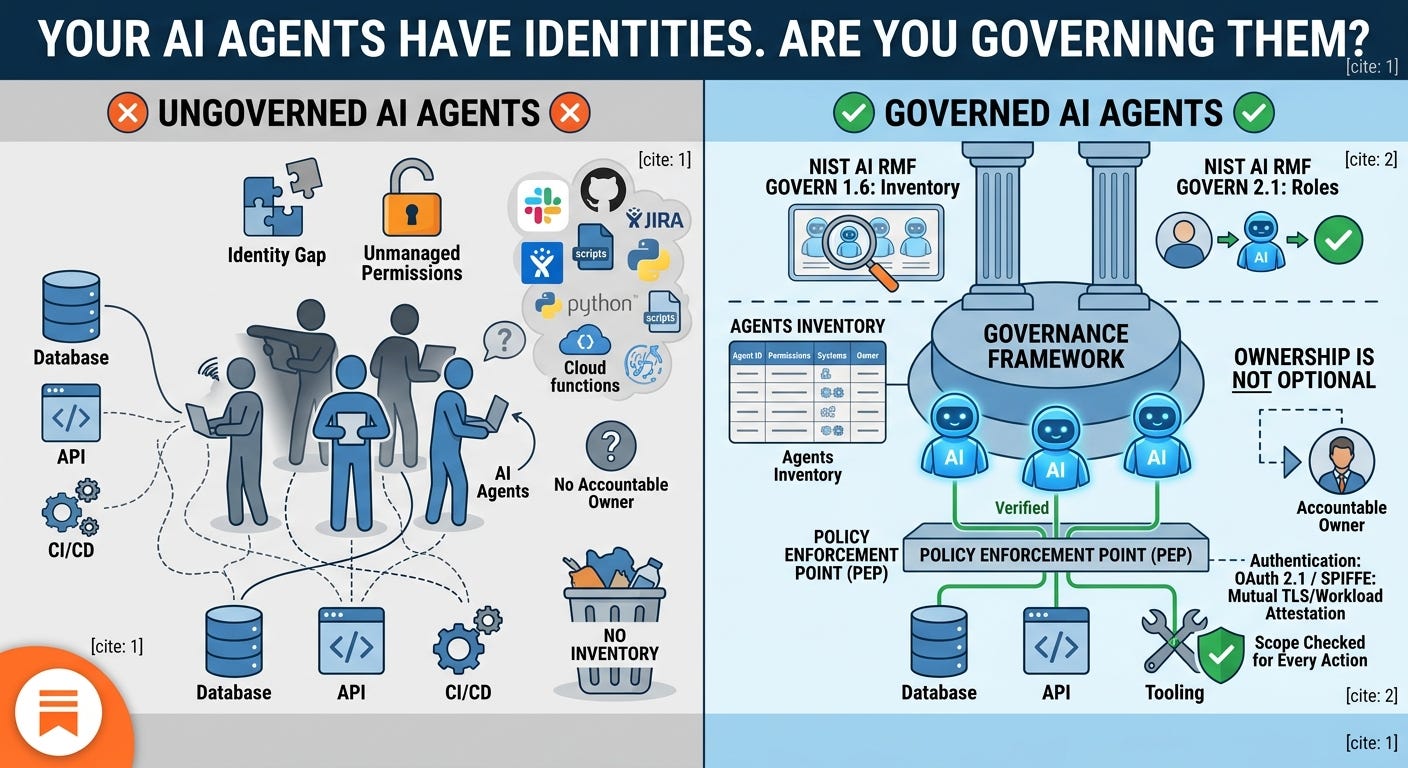
If you’ve read my GOVERN series on the NIST AI RMF, you already know the framework treats governance as the foundation everything else depends on. Here’s where that foundation is failing right now: AI agents.
SANS’s 2026 Agentic AI Threat Map, based on the OWASP Top 10 for Agentic Applications, makes a striking observation: eight of the ten threats are fundamentally identity and authorization failures. Not model hallucination. Not data poisoning. Identity.
That’s a governance problem before it’s a technical one, and it’s exactly the gap I keep finding when I look at how organizations are deploying agents.
The Inventory Problem
Ask your security team how many AI agents are running in your environment right now. Not how many you approved. How many are actually running, with what permissions, talking to what systems.
Most organizations can’t answer that. Agents get spun up inside a CI/CD pipeline, a customer service tool, an internal automation script, and nobody adds them to an inventory because nobody thinks of them as identities. They think of them as features.
That’s the mistake. An agent that can read a database, call an API, or trigger an action is operating through an identity with permissions, much like a service account or other non-human identity. If it’s not inventoried, you cannot govern it, and if you cannot govern it, you cannot secure it.
This maps directly to NIST AI RMF GOVERN 1.6, which addresses AI system inventory, and GOVERN 2.1, which addresses documented roles and responsibilities. MAP 1.1 is also relevant because it requires organizations to understand and document an AI system’s intended purpose, context, users, and potential impacts.
Ownership Is Not Optional
Every agent needs an accountable owner. In practice, that should normally include a named individual responsible for its lifecycle, even when operational ownership sits with a team.
When that person leaves the organization, what happens to the agent’s access? If you don’t have an answer, you have an orphaned identity with live permissions and no one accountable for reviewing them. This is the same succession problem you’d flag in any access review for a departing employee. Agents don’t get a pass because they’re software.
Scope Is a Contract, Not a Suggestion
Here’s where agentic AI diverges from traditional service accounts in a way that matters: agents take instructions in natural language, and natural language can be manipulated. Prompt injection is not a theoretical risk. It’s the mechanism by which an attacker gets an agent to act outside its intended scope without ever touching a credential.
The defense is not smarter prompting. It’s enforcement at the architecture level. Document what an agent is permitted to do before it deploys, and build the enforcement layer to check every action against that documented scope regardless of what instructions the agent received. Treat the scope document as a contract the system checks, not a policy the agent is trusted to follow.
This is why SANS’s Agentic AI Threat Map calls for a policy enforcement point sitting between the agent and its tools, authenticating and authorizing at the operational layer instead of just the connection layer. If your zero trust architecture stops at network access and doesn’t extend to what the agent does once it’s authenticated, you have a gap that will get found.
Authentication Standards Are Catching Up
Two important technologies in this space are OAuth 2.1 and SPIFFE. OAuth 2.1 remains an IETF Internet-Draft, while MCP’s authorization specification already incorporates OAuth 2.1 concepts for HTTP-based deployments.
The principle is simple even if the implementation isn’t: every agent-to-agent and agent-to-tool call should be treated as an explicitly authorized workload request, with the caller’s identity, permissions, intended resource, and applicable policy validated rather than implicitly trusted.
If you’re building on MCP right now, this is worth checking against your current implementation before you scale it, not after.
Detection Has to Assume Compromise Is Possible
Baseline normal agent behavior the same way you’d baseline a human account: request volume, API call patterns, destinations, time-of-day activity. An agent that suddenly requests an entire database or starts talking to a new destination is showing the same signal as a compromised human credential. Treat it the same way.
Honey tokens are worth the small setup cost here. Low effort, unambiguous signal. If an agent touches one, you know something is wrong.
And know your revocation procedure before you need it. How fast can you cut off a compromised agent’s access, and which systems require someone to manually intervene? Test it now. Don’t find out during an incident.
Where This Is Headed
NIST AI RMF, the EU AI Act, and ISO 42001 are converging on this exact set of requirements. If you’re building an AI governance program around any one of these frameworks, agent identity governance is not a future consideration.
The organizations that get ahead of this will treat their agents as what they are: identities with permissions, requiring the same inventory discipline, ownership accountability, and access governance you already apply to human users and service accounts. The ones that don’t will find out the hard way that eight out of ten threats to their agentic systems were sitting in plain sight.
I’m incorporating this control set into ENCLAVE-AI’s next assessment module. If you’re evaluating your own agent deployments against these controls, I’m interested in what gaps you’re finding.